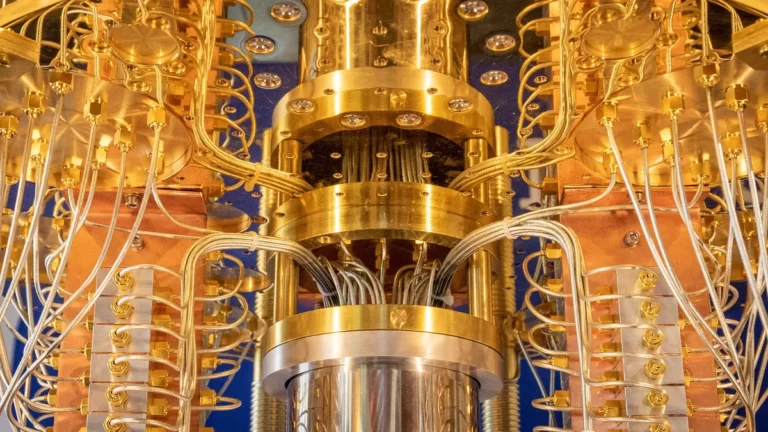
The fragile qubit
Quantum computers promise to solve problems that are intractable for classical machines — simulating molecules, optimizing vast systems, breaking today's encryption. But there is a catch that has haunted the field for decades: qubits are spectacularly fragile.
A classical bit is either 0 or 1, and it stays that way. A qubit, by contrast, lives in a delicate superposition of 0 and 1, and it can be entangled with other qubits in ways that have no classical analogue. The slightest disturbance — a stray photon, a tiny vibration, a whisper of heat — can collapse that superposition and corrupt the computation. This process is called decoherence, and on today's best hardware a qubit typically survives only tens to hundreds of microseconds before noise overwhelms it.
Worse, you cannot fight quantum errors the way classical computers fight theirs. Classical error correction is simple: make copies. Store every bit three times, and if one copy flips, the majority vote wins. But one of the deepest results in quantum mechanics — the no-cloning theorem — says it is impossible to make an exact copy of an unknown quantum state. The naive classical trick is forbidden by physics itself.
For years, this looked like a showstopper. Then, in 1995, Peter Shor proved it wasn't.
Protecting information without copying it
Shor's insight was subtle and beautiful: you don't need to copy a quantum state to protect it. Instead, you can spread one logical qubit across several physical qubits in an entangled state, so that no single physical qubit holds the information on its own — and therefore no single error can destroy it.
His original construction, the 9-qubit code, encodes one logical qubit into nine physical ones. A year later, Andrew Steane found a more efficient 7-qubit code. The key idea behind both: instead of measuring the qubits themselves (which would collapse the precious superposition), you measure relationships between them — parity checks that reveal what kind of error happened and where, without revealing the underlying data.
Think of it like a Sudoku puzzle. You never need to be told the value of a specific cell to know that a row is wrong — the constraints themselves expose the error. Quantum codes work the same way: carefully chosen joint measurements, called stabilizers, produce an error syndrome that diagnoses the problem while leaving the encoded information untouched. Once you know the syndrome, you know exactly which correction to apply.
This framework — stabilizer codes, formalized by Daniel Gottesman in the late 1990s — became the language of the entire field.
The surface code: error correction on a grid
Of all stabilizer codes, one family came to dominate hardware roadmaps: the surface code, descended from Alexei Kitaev's 1997 toric code proposal. Its appeal is practical. Qubits are arranged on a two-dimensional grid, and stabilizer measurements involve only neighboring qubits — exactly the kind of local operations that superconducting chips and other platforms can actually perform.
The code has a single tunable parameter: the code distance, d. Roughly speaking, a distance-d surface code arranges data qubits in a d×d patch and can correct any combination of up to (d−1)/2 physical errors. Bigger patch, stronger protection — at the cost of more physical qubits. A distance-3 code needs 9 data qubits (plus measurement helpers); distance 5 needs 25; distance 7 needs 49.
But there is a catch, and it leads to the most important theorem in the field.
The threshold theorem: the deal that makes it all work
Adding more physical qubits also adds more places for errors to occur. So a bigger code only helps if each individual qubit is already good enough. The threshold theorem — proved in the late 1990s by Knill, Laflamme, and Zurek, and independently by Aharonov and Ben-Or and by Kitaev — makes this precise:
If the physical error rate is below a certain threshold, then increasing the code distance suppresses the logical error rate exponentially.
For the surface code, that threshold sits around 0.5–1% error per operation. Below it, every step up in code distance multiplies reliability by a constant factor — errors fall off a cliff as you scale. Above it, adding qubits just adds noise, and the code makes things worse.
The theorem guaranteed that fault-tolerant quantum computing was possible in principle. But for nearly three decades, nobody could demonstrate the crucial scaling behavior in practice. Every experiment either used too few qubits, or showed errors getting worse as the system grew. The theory was sound; the hardware wasn't there yet.
December 2024: Willow bends the curve
That changed with Google's Willow chip. Willow is a 105-qubit superconducting processor, but the headline was not the qubit count — it was the first public demonstration of below-threshold quantum error correction.
Google's team ran surface codes at distances 3, 5, and 7 on the same chip. As the code grew — 9, then 25, then 49 data qubits — the logical error rate went down, exponentially. Each increase in code distance suppressed errors by a factor of about 2.1. At distance 7, the logical error rate reached 0.143% per error-correction cycle.
Even more striking: the logical qubit outlived the best physical qubit on the chip by a factor of 2.4. The encoded, error-corrected qubit was more reliable than any of its components — a milestone researchers call “beyond breakeven.” The whole had become greater than the sum of its parts. The result was published in Nature (Acharya et al., 2025; preprint at arXiv:2408.13687).
This was the moment the threshold theorem graduated from mathematics to engineering reality. The curve finally bends the right way.
How far is “useful”? The overhead problem
Before declaring victory, some honest accounting is in order. A logical error rate of 0.143% per cycle sounds impressive until you learn what real algorithms need: roughly one error per million operations (10−6) to run circuits deep enough for practical problems like simulating complex molecules or breaking RSA encryption.
Closing that gap requires much larger code distances — and the qubit overhead is steep. Depending on the algorithm and the hardware's physical error rate, a single useful logical qubit may demand hundreds to thousands of physical qubits. A machine capable of running Shor's algorithm against real-world key sizes might need on the order of a million physical qubits. Willow has 105.
The industry knows this, and roadmaps now revolve around it. Google is targeting a useful error-corrected machine around 2029, scaling through thousand-qubit intermediate systems. IBM's roadmap runs through its Starling system in 2029 with a fault-tolerant architecture. Meanwhile the field is diversifying: Quantinuum has demonstrated dozens of logical qubits on trapped-ion hardware, QuEra has shown 96 logical qubits on neutral atoms, and Microsoft's topological-qubit bet with Majorana 1 — still contested — aims to slash the overhead at the physics level rather than the code level.
The race is no longer about who has the most physical qubits. It is about who can manufacture the most logical ones, cheaply and reliably.
Why this matters
Quantum error correction is the difference between a physics experiment and a computer. Classical computing only took off once engineers could assume the hardware would not betray them — once abstraction layers like “a bit is a bit” became trustworthy. Logical qubits are the quantum equivalent of that abstraction: a reliable unit of quantum information built from unreliable parts.
Willow's result did not give us a useful quantum computer. What it gave us is arguably more important: proof that the path exists. For thirty years, fault tolerance was a theorem. Now it is a demonstration. The remaining challenge — enormous, but well-defined — is scale.
If you are learning quantum computing today, this is the single most important concept to internalize. Superposition and entanglement get the headlines, but error correction is what will decide whether quantum computers change the world or remain beautiful laboratory curiosities.
Further reading
- Acharya et al., “Quantum error correction below the surface code threshold,” Nature 2025 — preprint: arXiv:2408.13687
- Shor, “Scheme for reducing decoherence in quantum computer memory,” Physical Review A 52(4), 1995 — the paper that started it all
- A clear overview of the concepts and recent hardware milestones: quantumzeitgeist.com/what-is-quantum-error-correction